
The enterprise data lakehouse
Unified data analytics at scale
Break down data silos and unlock advanced analytics without losing control of your infrastructure. Canonical's AI analytics data lake stack offers a self-governed, enterprise-grade lakehouse built on open standards.
What is a data lakehouse?
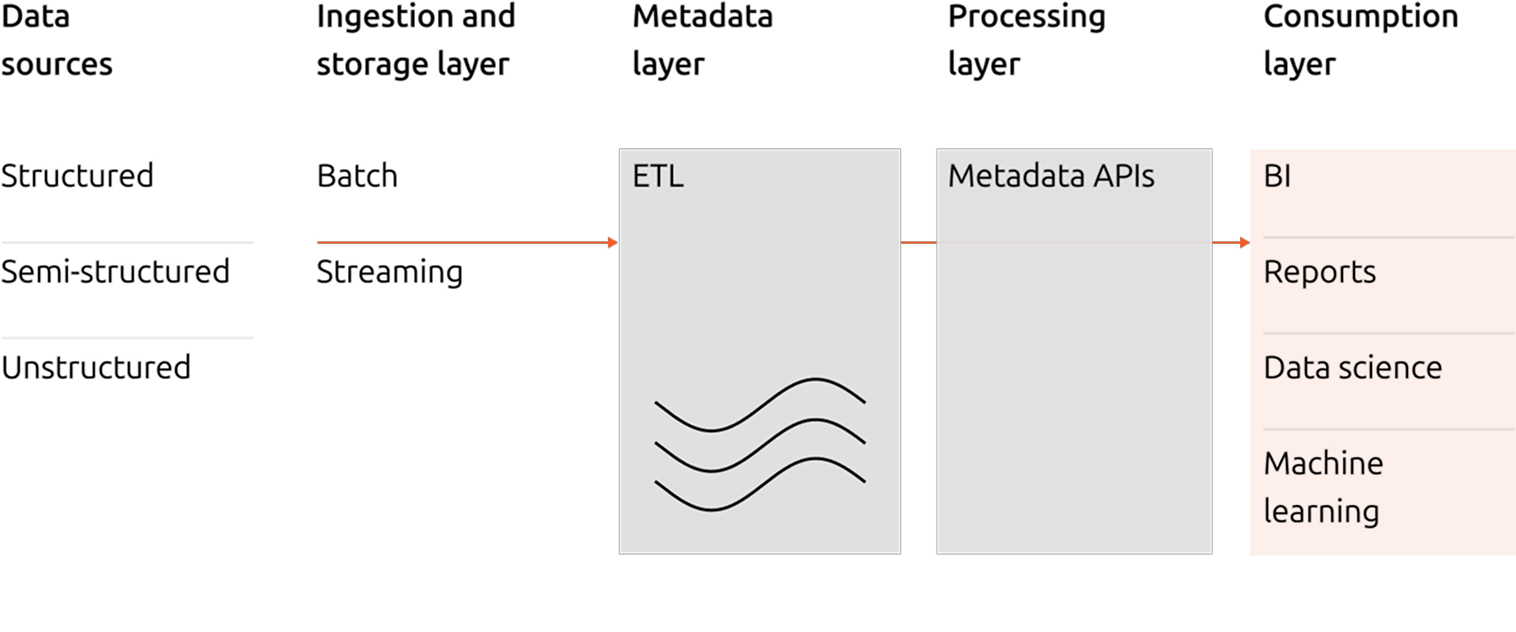
A data lakehouse is an architecture which combines the cost optimized scale of a data lake with the powerful analytical capabilities of a data warehouse.
Canonical's AI analytics data lake stack
Canonical's data lake stack has everything you need to build, scale, and operate your enterprise data lakehouse. Built on open source Ubuntu, Canonical's data lake stack brings you convenience, familiarity and up to 15 years of support.
Lakehouse foundations
Data ingestion and orchestration
Data governance and virtualization
Business intelligence and AI model serving
Go inside the Canonical AI analytics data lake stack
Discover the reference design ›
Lakehouse foundations
At the foundation of any lakehouse are core capabilities for compute, storage and governance. Canonical builds each layer on proven open source technologies, with GPU acceleration available when you need it.
- Core processing: Powered by Apache Spark for high-scale parallel compute.
- Software defined storage: Durable, efficient and massively scalable Ceph object storage.
- The open lakehouse: Uses Apache Polaris to ensure a governed, open data ecosystem.
- Hardware accelerated: Native NVIDIA CuDF plugin for Apache Spark enables GPU accelerated data processing.
Data ingestion and orchestration
A data lake is only useful when there's data. Canonical offers a full suite of data ingestion and orchestration capabilities to help you rapidly build reliable, scalable data pipelines and move data into the lake.
- Changed data capture: Stream transactional database changes into the lakehouse using Apache Kafka and Kafka Connect.
- SaaS connectors: Integrate platforms like GitHub and Salesforce via Airbyte.
- Workflows and scheduling: Coordinate complex operational graphs with Apache Airflow.

Federated governance & data virtualization
Canonical knows that establishing and enforcing policies and controls over who can work with what data is critical to the success of your data initiative. That's why we've integrated a suite of open source governance tools that work across your lakehouse, and beyond.
- Data virtualization: Trino queries across transactional databases and the lakehouse using standard SQL for near realtime analytics
- Granular security: Apache Ranger enforces row/column filtering and sensitive data redaction.
- Traceability: DataHub tracks data lineage from origin to destination for compliance.
Business intelligence and genAI model serving
For analytics, it's essential to have tools for reporting, spanning from visualization data science through to AI-assisted analysis. Canonical offers you the tools you need to understand what the data means.
- Visual analytics: Build high-performance dashboards with Apache Superset.
- Full MLOps suite: Operationalize data science workloads via Kubeflow and MLflow.
- High performance genAI: Serve open-weight models (like Qwen, Llama, and Kimi) behind your firewall using LLM-d and vLLM for conversational analytics, agentic coding and more.
Sign up for our data & AI newsletter
Get early access to beta programs and stay informed of new product releases.
Apache®, Apache Kafka, Kafka®, and the Kafka logo are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.
Apache®, Apache Polaris, Polaris®, and the Polaris logo are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.
Apache®, Apache Spark, Spark®, and the Spark logo are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.
Apache®, Apache Airflow, Airflow®, and the Airflow logo are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.
Apache®, Apache Ranger, Ranger®, and the Ranger logo are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.
Apache®, Apache Superset, Superset®, and the Superset logo are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.